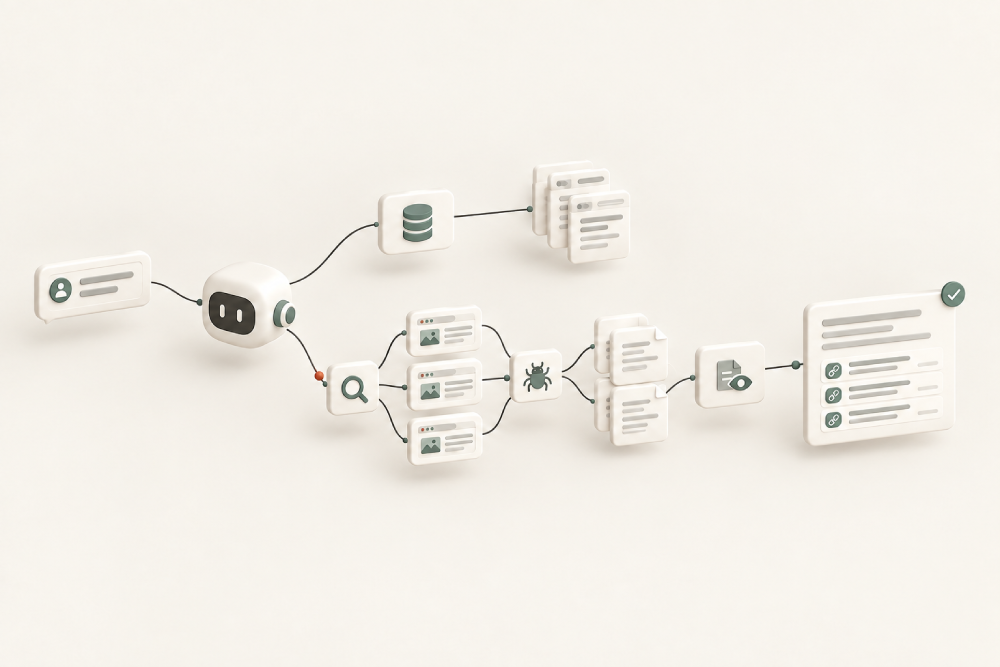
AI engines answer in one of two ways: from what the model learned in training, or by searching the web at the moment you ask. Only the second can cite a website. When ChatGPT, Claude or Google’s AI Mode does search, it turns your question into several background searches, fetches a handful of pages, reads passages from them and links some as sources. Whether it searches at all is the engine’s decision, and that decision can change from one day to the next.
The short version:
- Every AI answer comes from training data, a live search, or a mix of both. Only a live search produces citations
- Not every answer searches. In my own ChatGPT test on 23 September 2026, 2 of 10 answers used no search at all
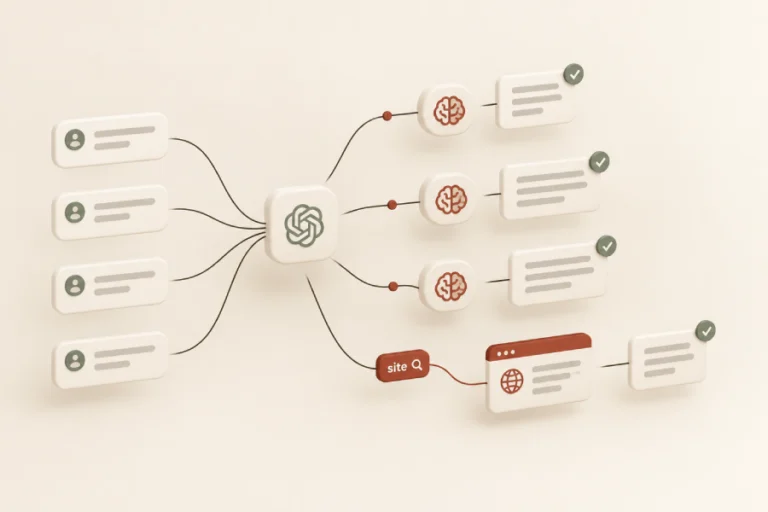
- One question becomes several searches. Google calls this query fan-out, and ChatGPT and Claude do the same thing
- For short “best X” questions, ChatGPT wrote brand names into its first search before a single result came back
- OpenAI and Anthropic each run separate crawlers for training and for search. Blocking one does not block the other
- Google-Extended is not a crawler, and it has no effect on Google’s AI Mode
- Google’s only stated requirement for AI Mode is that a page is indexed and eligible to show a snippet in Google Search
- A page can be fetched and still not be cited. Fetched, cited and mentioned are three different things
What is an AI engine, and how is it different from a search engine?
An AI engine writes an answer to a question, while a search engine returns a list of pages that might contain one. ChatGPT, Claude and Google’s AI Mode are all AI engines built on large language models. When they use the web, they show the pages they drew on as citations, which means a website is cited in an AI answer rather than ranked in it. There is no public position one to ten inside an AI answer.
A large language model (LLM) is the part that writes. It predicts text from patterns learned during training, and on its own it knows nothing that happened after its training data was collected. Everything an AI engine adds on top of the model, including the ability to search the web, exists to work around that limit.
Is “AI search” one system?
No. ChatGPT, Claude and Google’s AI Mode are three separate systems with separate models, separate crawlers and separate ways of searching the web. Google’s AI Mode is part of Google Search and draws on Google’s own index. ChatGPT and Claude are built by OpenAI and Anthropic, run their own crawlers, and are not Google products. A change at one of them does not move the other two.
Google also runs AI Overviews, the AI summary shown at the top of ordinary Google results. AI Overviews is a different product from AI Mode, and this article covers AI Mode only.
Where do AI engines get their information: training data or a live search?
AI engines get their information from two places: the training data the model learned from before it was released, and pages fetched from the web at the moment a question is asked. The first is fixed and carries no sources. The second is live and carries citations. Most answers people see are one or the other, or training data with a search layered on top, and almost everything a website owner can influence sits in the second.
| Training data | Live retrieval (a search) | |
|---|---|---|
| When it happens | Before the model is released | At the moment the question is asked |
| What it is made of | A very large collection of text the model learned patterns from | Search results and pages fetched just now |
| How fresh it is | Fixed at a training cutoff date | As fresh as the pages fetched |
| Can it show sources? | No | Yes. This is where citations come from |
| Which crawler feeds it | Training crawlers, such as OpenAI’s GPTBot and Anthropic’s ClaudeBot | Search crawlers, such as OAI-SearchBot, Claude-SearchBot and Googlebot |
| Can a website change it? | Not for the model answering today | Yes, by being findable, fetchable and readable |
What is training data, and can a website add itself to it?
Training data is the text a model learned from before release, and no website can add itself to the model answering questions today. Allowing a training crawler such as GPTBot or ClaudeBot makes your pages available for future training runs. It does not change the current model, and nothing guarantees that any particular page is used. Anyone offering to “get you into ChatGPT’s knowledge” is describing something nobody outside OpenAI controls.
Training data explains why an AI engine can describe a well-known business without searching. The business was written about widely enough, before the cutoff, for the model to have learned it. The same mechanism explains why a newer or smaller business is simply absent from answers that come from the model alone.
What is live retrieval, and what do “grounding” and “RAG” mean?
Live retrieval means the engine searches the web while it answers and writes from the pages it found. Google calls this grounding, and its own crawler documentation defines it as “providing content from the Google Search index to the model at prompt time to improve factuality and relevancy”. The general technical term is retrieval-augmented generation, or RAG. All three names describe the same idea: fetch first, then write.
Retrieval is the only point at which a page on your website can enter an AI answer as a cited source. It is also the only point where anything you do to your site this month can make a difference this month.
Why does the difference matter for a website?
The difference matters because the two paths have different levers, and most advice pulls the wrong one. Blocking or allowing a training crawler changes what future models may learn from. It does not decide whether a search crawler can fetch your page tomorrow. Being cited depends on the retrieval path, so the work that affects citations is the work that makes a page findable, fetchable and readable when an engine searches.
How does an AI engine decide whether to search the web?
The engine decides for itself, question by question, and each company describes the rule only in general terms. OpenAI, Anthropic and Google all say the engine searches when a question benefits from current or specific information and answers from the model when it does not. None of them publishes the exact threshold, and in practice the same question can go either way on different days.
What do OpenAI, Anthropic and Google say about when their AI searches?
| Engine | What the company says | Source |
|---|---|---|
| ChatGPT | “ChatGPT may search the web automatically when your question would benefit from current information.” | OpenAI Help Center, ChatGPT search |
| Claude | “Claude searches the web when it helps.” Anthropic’s developer documentation lists recent events, current prices and “specific organizations, people, or products that might have changed” as reasons to search, and “established facts” as reasons not to | Claude Help Center · Claude web search tool docs |
| Google’s AI Mode | AI Mode is part of Google Search and uses “a ‘query fan-out’ technique, issuing multiple related searches concurrently across subtopics and multiple data sources” | Google, 5 March 2025 |
Anthropic’s list is the most useful of the three for a business owner, because it names the category most businesses fall into. A question about a specific organisation or product “that might have changed” is, by Anthropic’s own description, a reason for Claude to search rather than rely on what it learned.
How often does an AI engine answer without searching?
Often enough to matter. In my own ChatGPT test on 23 September 2026, 2 of 10 answers used no web search at all, and both were short, general questions. I asked “is a heat pump worth it” and “how to choose a wedding photographer”, and ChatGPT answered both from the model, with no sources shown. The longer, more specific versions of the same two questions both triggered a search.
| Question | Searched? | What that meant |
|---|---|---|
| “is a heat pump worth it” | No | Answered from the model. No sources, no citations |
| “how to choose a wedding photographer” | No | A long checklist written entirely without a search |
| The same two topics, asked in detail | Yes, both | Searches ran and sources were cited |
The same thing happens on Claude. The same question, asked on 2 September 2026 and again on 13 September 2026, searched the web the first time and answered from memory the second time, citing nobody. I reported that in my article on how to measure whether AI actually cites your business. A search is never guaranteed, even for a question that searched last time.
The method behind the ChatGPT figures: ten prompts on 23 September 2026, run in a temporary chat on the Free plan, where ChatGPT answered with a model it labels gpt-5-6-mini. I read whether a search ran, and exactly what was searched, from the search_model_queries field in ChatGPT’s own response data, visible in the browser’s developer tools. One run, one account, one model: this shows the mechanism, not a rate you should expect on your own questions.
What is query fan-out in AI search?
Query fan-out is the step where an AI engine turns one question into several background searches, then combines what comes back into a single answer. Google uses the term for AI Mode and AI Overviews, describing it as “issuing multiple related searches across subtopics and data sources”. ChatGPT and Claude do the same. The searches are usually shorter and more keyword-like than the question, and the person asking never sees them.
Fan-out is why an AI answer can cite pages that do not match your question word for word. The engine was not searching for your question. It was searching for the pieces it decided your question was made of.
What does query fan-out look like inside ChatGPT?
Inside ChatGPT, one short question produced three searches, and the first one already named four brands. I asked “best password manager”. Before any result came back, ChatGPT searched for “best password managers 2026 1Password Bitwarden Proton Pass Dashlane”, then ran one search each for 1Password and Bitwarden with the word “official” added. The recommendation came from brands the model had already chosen.
Does the AI decide the shortlist before it searches?
For short “best X” questions in my test, yes: ChatGPT wrote its shortlist into the first search every time it searched. “best password manager”, “best running shoes flat feet” and “best carry-on backpack” each produced a first search that already contained named brands or products. The search then checked the shortlist rather than building one. Being on that list depended on the model, not on who ranked for the question.
| What I asked | Names in the first search that were not in my question |
|---|---|
| best password manager | 1Password, Bitwarden, Proton Pass, Dashlane |
| best running shoes flat feet | Brooks Adrenaline, ASICS Kayano, Saucony Guide |
| best carry-on backpack | Osprey Farpoint 40, Cotopaxi Allpa 35, Patagonia Black Hole MLC 45 |
A longer question behaved differently, and more tellingly. I asked about running shoes for a beginner with flat feet and knee pain. ChatGPT searched only for medical evidence, cited research papers, and still recommended four named shoes. No search looked for those shoes. The product picks came from the model alone, and the search was there to support the health claim.
Does query fan-out behaviour change over time?
Yes, and without notice. The engines change how they write their background searches, and a pattern that held last month may not hold today. What ChatGPT’s searches looked like after its August 2026 change is the subject of a separate article, where I tested it directly.
Which AI crawlers visit your website, and what does each one do?
AI companies send different crawlers for different jobs: one collects training data, one builds a search index, and one fetches a page when a user asks for it. OpenAI and Anthropic each publish all three by name. Google works differently, because AI Mode is part of Google Search and uses Googlebot. Each crawler obeys its own line in robots.txt, so blocking one does not block the others.
| The job | OpenAI (ChatGPT) | Anthropic (Claude) | Google (AI Mode) |
|---|---|---|---|
| Collect training data | GPTBot | ClaudeBot | Googlebot crawls; the Google-Extended token controls training use |
| Build the search index answers draw on | OAI-SearchBot | Claude-SearchBot | Googlebot |
| Fetch a page because a user asked | ChatGPT-User | Claude-User | None listed for AI Mode. Google-Agent fetches for agents acting on a user’s request |
OpenAI’s own documentation is explicit about the consequence. Sites that block OAI-SearchBot “will not be shown in ChatGPT search answers”, while blocking GPTBot only means content “should not be used in training generative AI foundation models”. For ChatGPT-User, OpenAI notes that “because these actions are initiated by a user, robots.txt rules may not apply”. Sources: OpenAI’s crawler documentation and Anthropic’s crawler documentation, both read on 23 September 2026.
Is Google-Extended a crawler?
No. Google-Extended is a robots.txt token, not a crawler, and it does not affect Google Search or AI Mode. Google’s common crawlers documentation says it “doesn’t have a separate HTTP request user agent string”. It controls whether content Google has already crawled may be used to train Gemini models and to ground answers in the Gemini app and Vertex AI, and it “does not impact a site’s inclusion in Google Search”.
Blocking Google-Extended to stay out of AI Mode therefore does nothing to AI Mode, which is a common and expensive misunderstanding. AI Mode is Search, and it is controlled by the same things that control Search.
How does an AI engine read a page it has fetched?
An AI engine reads what the server sends and pulls passages from it, rather than taking in the page the way a visitor sees it. Google says a page must have “indexable content” to be considered at all. Anthropic’s developer documentation shows Claude’s citations quoting a passage of up to 150 characters, not a whole page. The practical result is the same everywhere: the answer is built from short passages, not whole pages.
Does an AI crawler see the server’s HTML or the finished page?
Assume it sees only the HTML your server sends before any JavaScript runs. Google renders JavaScript for Search, but its own JavaScript documentation warns that “not all bots can run JavaScript”. Neither OpenAI nor Anthropic documents that its fetchers run JavaScript at all. Content that only appears after a script runs may be invisible to the fetcher that matters.
I found this on my own site. The “Recent writing” cards on the theshiva.co home page are added by JavaScript after the page loads, and in the HTML the server sends there was not a single link to a blog post. A visitor saw the latest articles. A fetcher saw none of them. The fix was a plain text link in the server HTML.
Does an AI engine read the whole page or only parts of it?
An AI engine works from parts of a page, which is why each paragraph needs to make sense on its own. Anthropic’s developer documentation for Claude’s web search returns each citation as a quoted passage, the cited_text field, of up to 150 characters. A paragraph that opens with “This means” or “As mentioned above” depends on text the engine may never have read, and a passage that answers its own question completely is the one that can be lifted and cited.
How an automated agent reads the structure of a page is a separate question, covered in my article on what Agentic Browsing in PageSpeed Insights actually checks. A file listing your pages for AI does not change any of this either, as I found when I tested whether llms.txt actually does anything.
Why do AI engines cite some pages and not others?
An AI engine cites the pages whose passages it actually used, from among the pages its searches returned. A page has to be found by a search, fetched, readable, and then useful for the specific answer being written. Many pages pass the first three steps and fail the fourth. None of the three companies publishes how the final choice is made, so what follows is what the documentation allows and what I have observed.
What is the difference between fetched, cited and mentioned?
| Term | What it means | Can you see it? |
|---|---|---|
| Fetched | A crawler requested the page while building an answer | Only in your server logs |
| Cited | The page is linked as a source in the answer | Yes, in the answer |
| Mentioned | Your business is named in the answer, with or without a link | Yes, but it may come from training data, not from your site |
Anthropic’s documentation separates the first two in its own data: search results come back as a list of pages, and citations are a separate item carrying the quoted passage. A page can be in the results and never quoted. A business can also be mentioned with no citation at all, as the running-shoe answer showed: four named products, none of them searched for.
What kinds of sources did the engines cite in practice?
In my ChatGPT run, the question decided the kind of source. A detailed question about password managers for a couple cited only the brands’ own websites. The backpack and running-shoe shortlists cited review and gear sites. The medical question cited research papers. The detailed wedding-photographer question cited a wedding-planning site and a photographers’ association. Reddit appeared in none of the visible sources across the ten answers.
The broader pattern, across 75 answers on three engines, is in my measurement article: businesses were named on 73% of questions that used their name and on 0% of shortlist questions.
How are ChatGPT, Claude and Google’s AI Mode different?
ChatGPT, Claude and Google’s AI Mode differ in whose index they search, which crawler fetches your pages, and how much each company discloses. AI Mode draws on Google’s own Search index. ChatGPT uses OpenAI’s own crawler alongside search partners OpenAI does not name on its help page. Anthropic runs Claude-SearchBot and does not name a web search provider in the documentation I read. Treating the three as one system produces advice that fits none of them.
| ChatGPT | Claude | Google’s AI Mode | |
|---|---|---|---|
| Made by | OpenAI | Anthropic | |
| Where searches go | OpenAI’s index, plus “other search providers” (unnamed) | Not named in Anthropic’s documentation | Google’s Search index |
| Search crawler to allow | OAI-SearchBot | Claude-SearchBot | Googlebot |
| Stated requirement to appear | Allow OAI-SearchBot, and let OpenAI’s IP addresses through your host or CDN | None published beyond robots.txt access | Indexed and eligible to show a snippet. “No additional requirements” |
| How it tags visits it sends | utm_source=chatgpt.com on referral links | Not documented | Counted in Organic Search |
Sources: OpenAI’s ChatGPT search help page, OpenAI’s publishers FAQ, Anthropic’s web search documentation and Google’s AI features and your website, all read on 23 and 24 September 2026.
What can’t a website owner control about AI citations?
A website owner cannot control what a model learned in training, whether the engine searches, what it searches for, or which of the fetched pages it cites. The engine also adapts answers to the person asking. In my test, ChatGPT added a section for the country my account is in without being asked, and on another question assumed a different country from the wording alone. Nobody can promise a citation, and anyone who does is promising something the engines do not offer.
- Training data. Fixed for the current model. Nothing you publish today changes it
- Whether a search happens. The engine decides per question, and the decision varies
- The shortlist. For “best X” questions it may be written before the search starts
- Personalisation. Location, chat history and account memory all shape the answer
- A ranking. There is no position to climb and no public index of AI answers
What can a website owner do to be cited by AI engines?
A website owner can make sure every page is findable, fetchable and readable at the moment an engine searches. That means letting the search crawlers in, being properly indexed in Google, putting important content in the HTML the server sends, and writing passages that answer a question on their own. None of it guarantees a citation. All of it removes a reason not to be cited.
- Allow the search crawlers. Check robots.txt for OAI-SearchBot, Claude-SearchBot and Googlebot. Decide on the training crawlers separately, as a separate question
- Check your host and CDN. OpenAI asks sites to allow traffic from its published IP addresses. A firewall can block a crawler that robots.txt allows
- Be indexed and snippet-eligible in Google. Google’s stated requirement for AI Mode.
nosnippetandnoindexlimit it - Put the content in the server HTML. Anything that only appears after JavaScript runs may never reach a fetcher
- Write passages that stand alone. Answer the question in the first sentence under each heading, and name the subject in every paragraph
- Measure before and after. Record what the engines say about you today, so later changes can be attributed. My measurement article sets out how
If you want to know which of these is the reason the engines are not citing your business, that is what an AI visibility audit establishes.
Your questions, answered
Does ChatGPT search the internet for every answer?
No. OpenAI says ChatGPT “may search the web automatically when your question would benefit from current information”, which means some answers come from the model alone. In my own test on 23 September 2026, 2 of 10 ChatGPT answers used no search at all, and both were short, general questions.
Where does ChatGPT get its information from?
ChatGPT gets its information from two places: the data its model was trained on, and web pages it searches for and fetches while answering. Only the second produces citations. OpenAI’s search crawler, OAI-SearchBot, builds the index ChatGPT search draws on, and OpenAI says it also works with other search providers it does not name on its help page.
Can I get my website into ChatGPT’s training data?
Not into the model answering questions today. Allowing OpenAI’s training crawler, GPTBot, makes your pages available for future training, but nothing guarantees any page is used, and the current model does not change. Being cited by ChatGPT depends on its search path, not on its training data.
Does blocking GPTBot stop ChatGPT from citing my site?
No. GPTBot collects training data, and ChatGPT’s search answers depend on a different crawler, OAI-SearchBot. OpenAI’s documentation states that each setting is independent. Blocking OAI-SearchBot is what removes a site from ChatGPT’s search answers.
Does Google-Extended affect Google’s AI Mode?
No. Google-Extended is a robots.txt token, not a crawler, and Google states that it “does not impact a site’s inclusion in Google Search”. It controls whether content can be used to train Gemini models and to ground answers in the Gemini app and Vertex AI. AI Mode is part of Google Search.
Do ChatGPT, Claude and Google’s AI Mode use the same search index?
No. Google’s AI Mode uses Google’s own Search index. ChatGPT uses OpenAI’s index built by OAI-SearchBot plus unnamed search partners. Anthropic runs Claude-SearchBot and does not name a search provider in the documentation I read. Being visible in one engine says little about the other two.
Does llms.txt help AI engines find my site?
Not for being cited. Google Search states that it ignores the file, and there is no published evidence that ChatGPT or Claude use it when answering questions about a business. I read nine of these files for my article on whether llms.txt actually does anything.
Why did the same question give a different answer the next day?
Because the engine decides afresh each time whether to search and what to search for, and it adapts to the person asking. On Claude, the same question searched the web on 2 September 2026 and answered from memory on 13 September 2026. A single answer is a sample, not a result.
How do I know if an AI engine cited my site?
Partly. ChatGPT adds utm_source=chatgpt.com to referral links, so visits from its citations can be seen in analytics. Google Search Console reports impressions in AI Overviews and AI Mode. Nothing reports how often ChatGPT or Claude showed your site without a click. My measurement article covers what each source can and cannot see.
The short of it
An AI engine answers from training or from a search, and only the search can cite you. Everything a website owner can usefully do sits on that second road: be findable when the engine searches, fetchable when its crawler arrives, and readable when it pulls a passage. The first road belongs to the model, and no amount of work on your site this month will change what it already knows.
The part most advice skips is the fork itself. Before any of your pages is read, the engine has decided whether to look at all, and on a short question it may have decided who is in the running too.